Consistent Hashing
Consistent hashing is a scheme for mapping keys onto a set of buckets (workers, shards, nodes) with one special property: when a bucket joins or leaves, only ~1/N of the keys move (where N is the new bucket count). A naive (mod (hash k) n) remaps nearly every key on every resize.
That property is what makes it the standard technique behind distributed caches (Memcached clients, Dynamo, Riak), load balancers, and — for our purposes — partitioned message processing: routing each key to a queue bucket while keeping the ordering intact when the fleet of workers changes.
Fundamentals — the hash ring
The idea (Karger et al., 1997):
- Hash the key into a large space (e.g., 64-bit), and arrange that space as a circle — the ring.
- Place each worker at one or more points on the ring (its
vnode/ token). - A key belongs to the first worker encountered walking clockwise from the key’s position.
        hash(key)
            │
            ▼
         ◄───────────────►  clockwise →
        (                  )
    w3 (      K1          ) w0
       (      │           )
        ( ────▼──────── )
         w2 (  w1 )

  K1 hashes just before w0's vnode → assigned to w0
The hash ring space is just a sorted circle; “find next vnode clockwise” is a successor lookup over sorted positions:
ring positions (v0 < v1 < v2 < v3 ... < v15 wrapped):

  key_hash(K1) = 9   → successor = v9   → bucket = owner(v9)
  key_hash(K2) = 14  → successor = v14  → bucket = owner(v14)
  key_hash(K3) = 3   → successor = v3   → bucket = owner(v3)
Virtual nodes (vnodes)
A virtual node is one of a bucket’s multiple placements on the ring. Instead of one point per bucket (Cassandra’s original token design), each bucket gets V points (typically 128–1024) spread around the circle:
- Balance — 3 buckets × 100 vnodes statistically interleave, so each bucket owns close to a 1/3 slice of the ring even with skewed hash distributions.
- Graceful failure — when a bucket dies, its vnodes are taken over by many successors, so load spreads across the rest rather than dumping onto one neighbor (the problem with naive “next node” rings).
- Minimal reshuffle on growth — a new bucket’s vnodes sit at random points; only keys in those narrow spans move.
Variants used in the wild instead of vnodes:
| Scheme | Idea | Trade-off |
|---|---|---|
| vnode ring (Cassandra, Dynamo) | many tokens per bucket | tune clone to balance; simple |
| Jump hash (Google) | jump(k, n) — minimal-disruption, only n param | O(log n), no ring concept, can’t span multiple keys/racks |
| Rendezvous / HRW (memcached clients) | pick bucket with the largest hash(k ∥ b) | min movement, but O(b) per lookup |
The ring in Clojure
A ring is a sorted-map of [vnode-hash → bucket]; lookup is a successor query:
(defn ring
  "Build a consistent-hash ring. workers: seq of bucket ids,
   vnodes: virtual points each bucket owns."
  [workers vnodes]
  (into (sorted-map)
        (for [w workers, v (range vnodes)]
          [(hash (str w ":" v)) w])))

(defn bucket
  "First bucket walking clockwise from (hash k)."
  [ring k]
  (or (second (first (subseq ring >= (hash k))))  ;; smallest vnode ≥ h
      (second (first ring))))                     ;; wraps around
(Use a real hash — murmur3 / md5 — in production; clojure.core/hash is fine for this example but not stable distribution across processes. For jump hashing: (ch (hash k) n-buckets).)
A demo on a 4-worker/top-level ring (4 vnodes each):
(def rg (ring [:w0 :w1 :w2 :w3] 4))

(bucket rg "user:42")   ;; => :w1
(bucket rg "user:42")   ;; => :w1  — deterministic
(bucket rg "chat:7")    ;; => :w2
(bucket rg "order:991") ;; => :w0
When a 5th worker :w4 joins, only the keys whose successor now sits inside :w4’s 4 new vnode spans change bucket — roughly 1/5 of keys, instead of every key.
Ordered processing — one consumer per bucket
Consistent hashing distributes; it doesn’t order. Ordering comes from the second rule: each bucket’s queue is consumed by exactly one worker, so messages for the same key are always dequeued and processed in FIFO order — while different keys on different buckets run in parallel.
(require '[clojure.core.async :as a])

;; one dedicated thread per bucket — `a/thread` (NOT `go`) so blocking
;; handle calls can't stall the async thread pool
(defn start-workers [n handle]
  (let [queues (vec (repeatedly n (a/chan 1024)))]
    (doseq [q queues]
      (a/thread (loop []
                  (when-let [msg (a/<!! q)]
                    (handle msg)
                    (recur)))))
    queues))

;; dispatcher: key → ring → single queue (always the same one per key)
(defn dispatch [bucket-fn queues msg]
  (a/>! (nth queues (bucket-fn (:key msg))) msg))
Deterministic routing:
msg {:key "user:42"}   bucket :w1   queue 0 → worker 0   (serial: 6, 5, 4 …)
msg {:key "user:42"}   bucket :w1   queue 0 → worker 0   (same queue, FIFO)
msg {:key "chat:7"}    bucket :w2   queue 1 → worker 1   (parallel — different bucket)
The diagram below shows the whole pipeline — ring lookup, fan-out to queues, one consumer per queue:
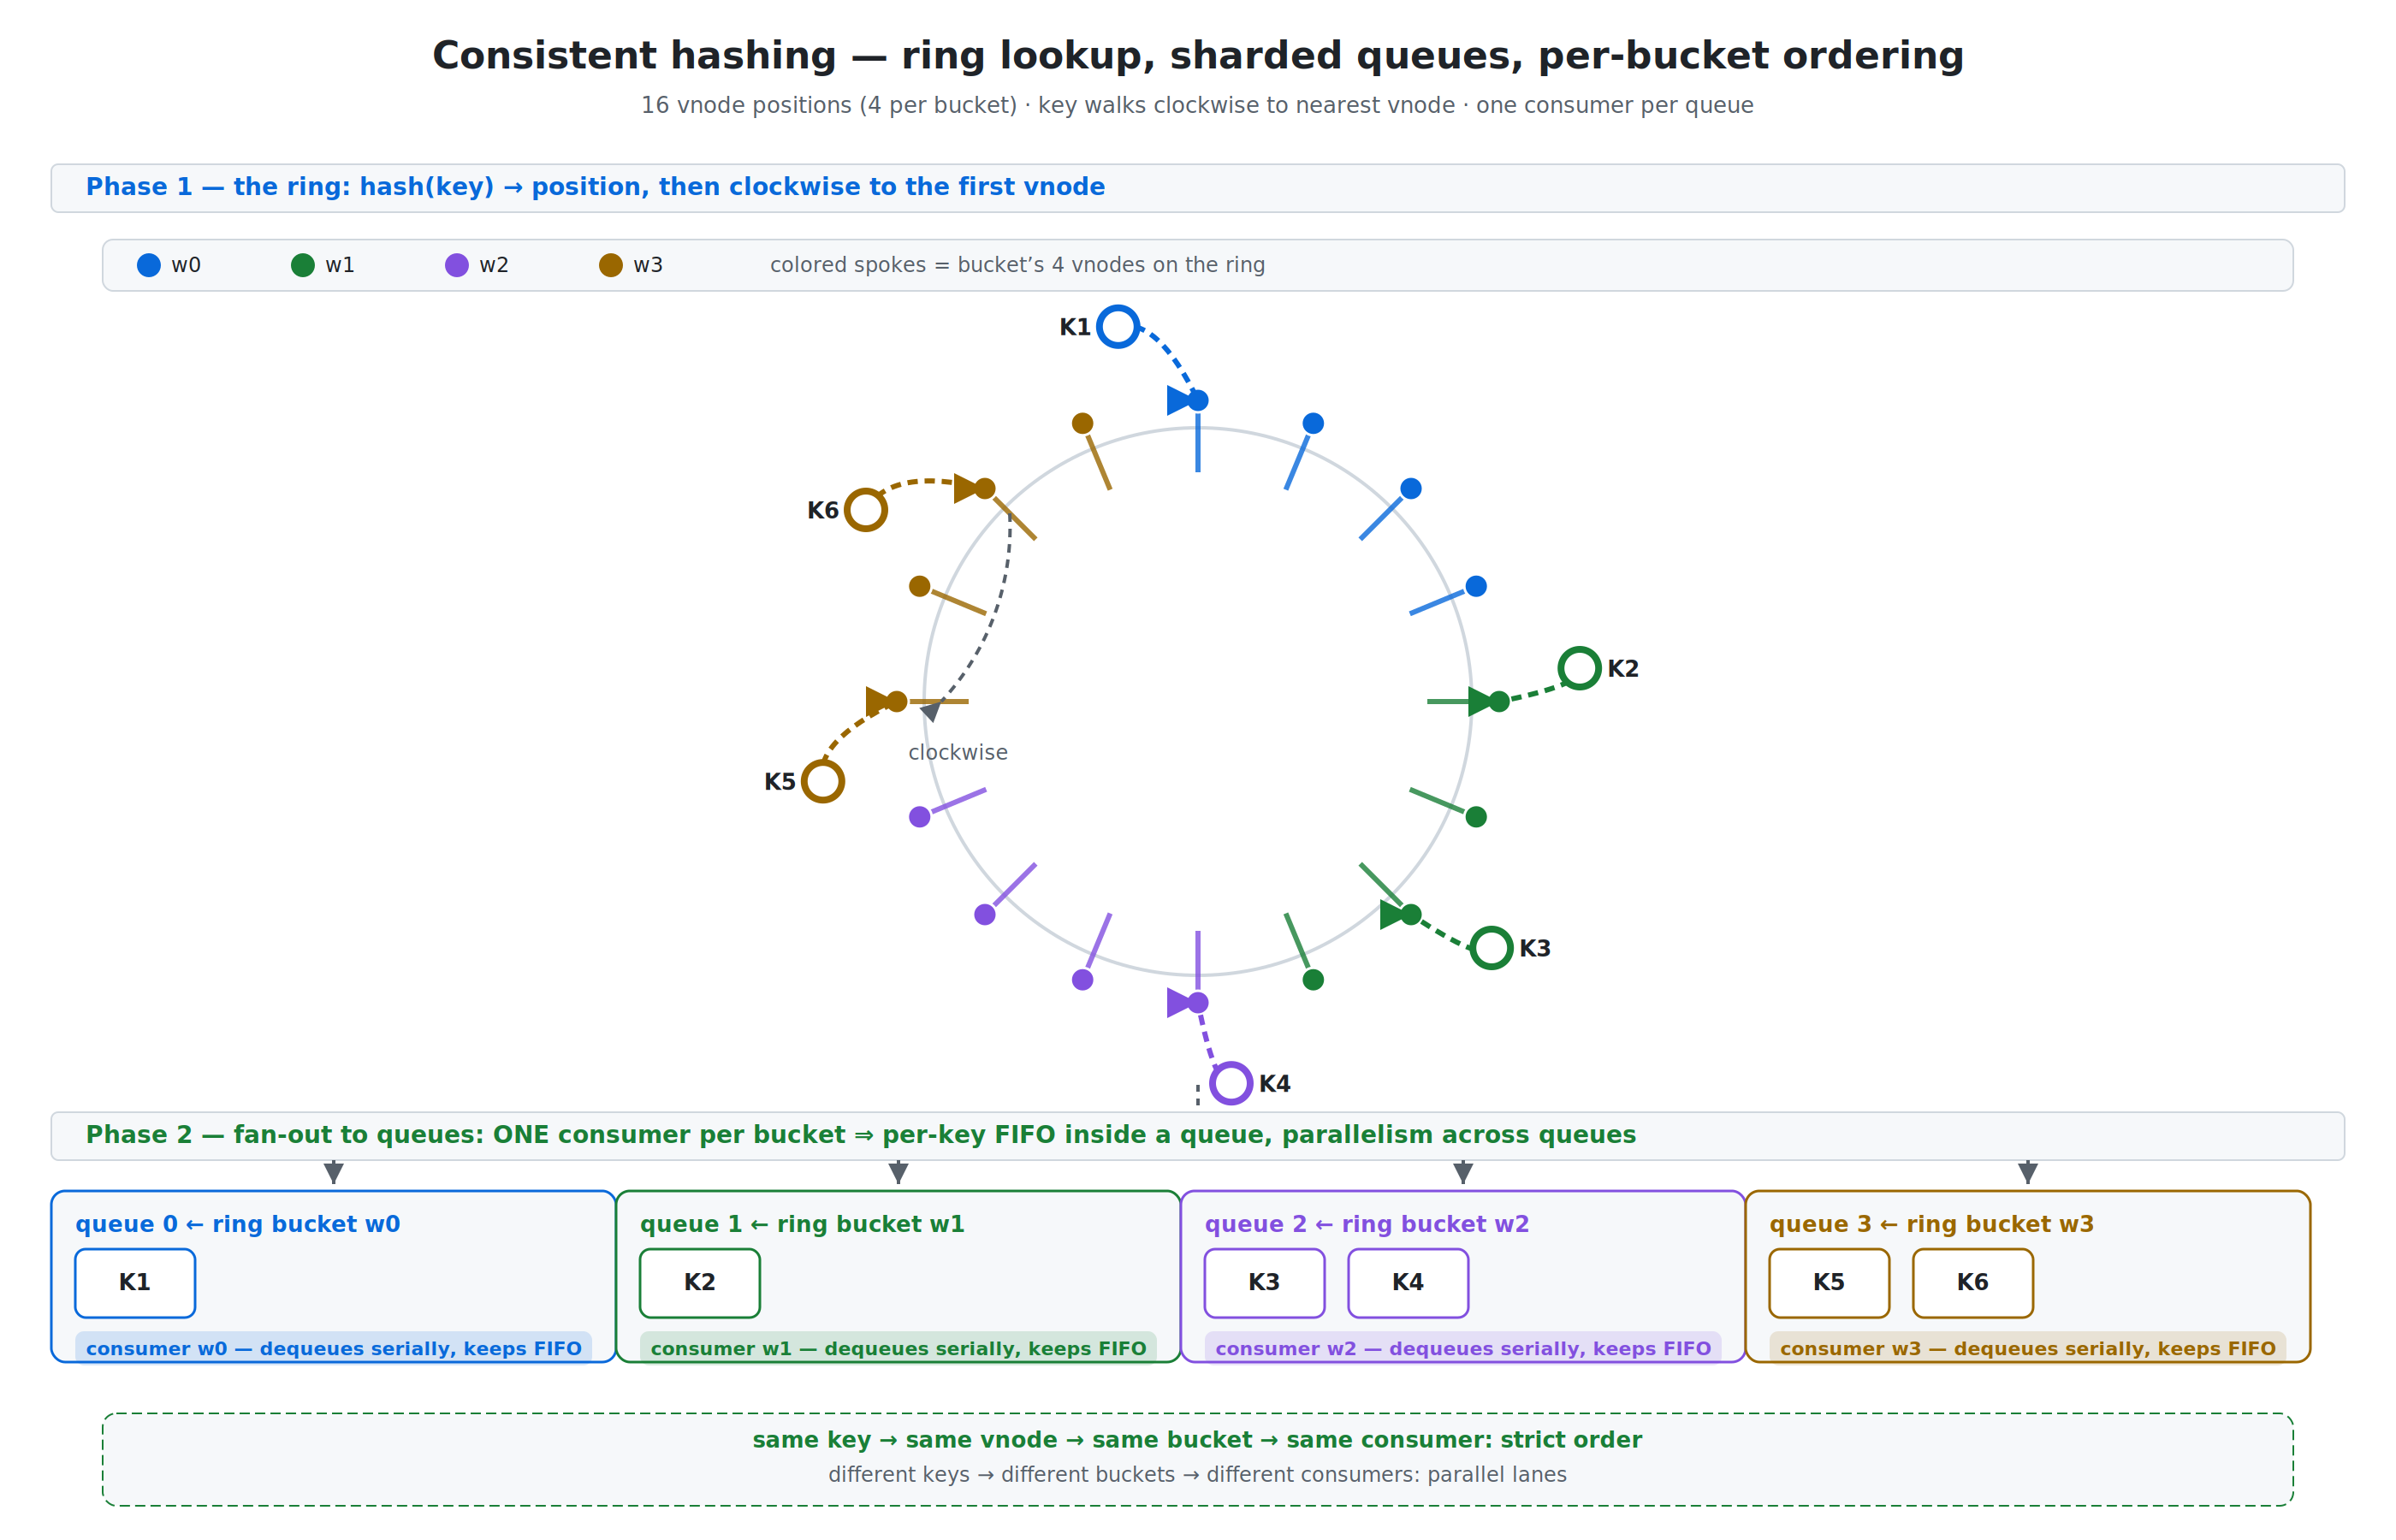
The SVG source is also available in the site repository.
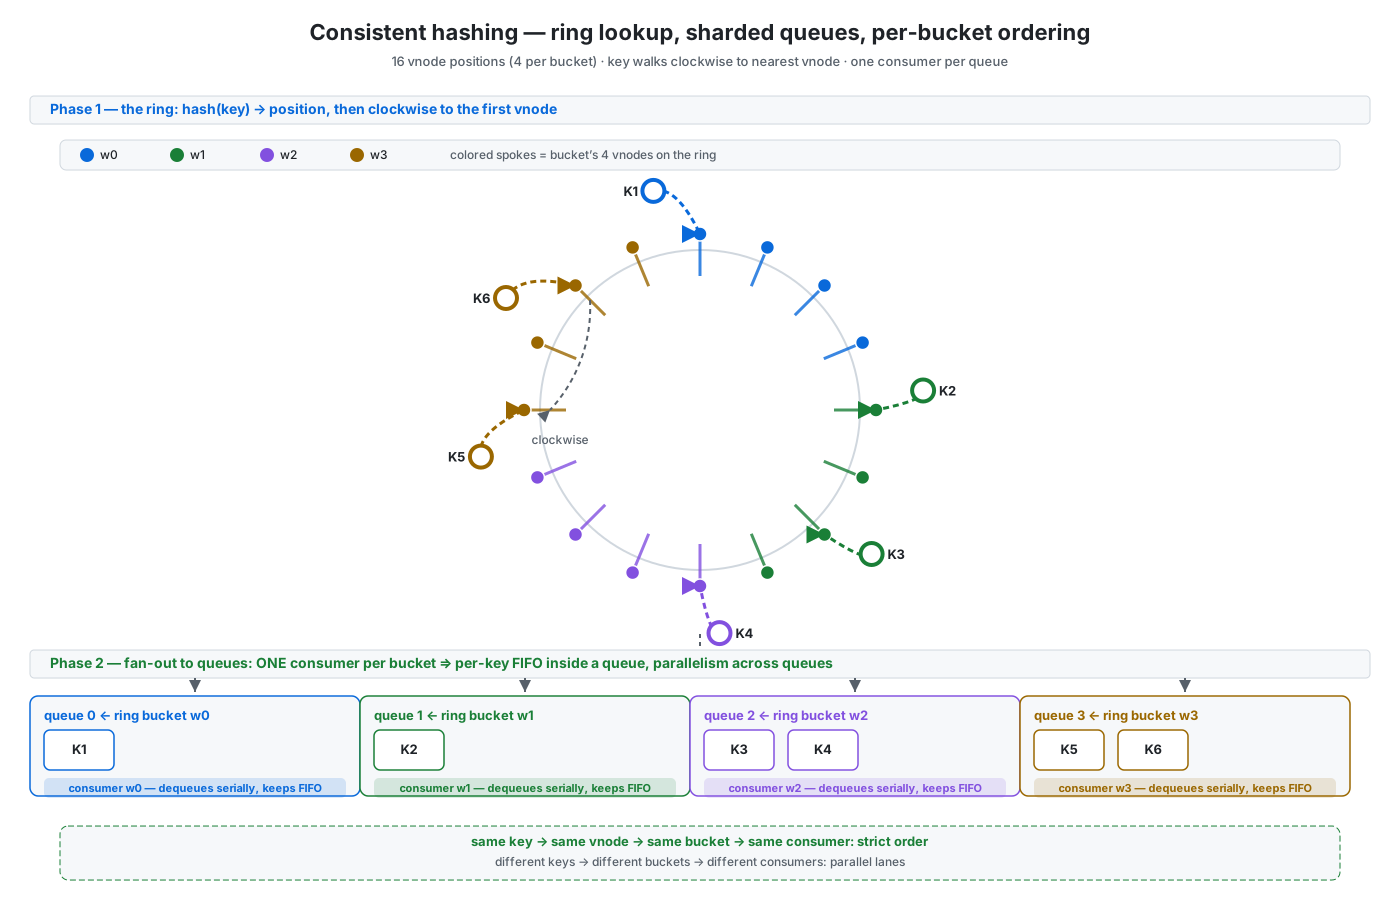
Top half — the hash ring: 16 vnodes, 4 per worker (w0…w3). Each key (K1…K6) sits at its hash position and walks clockwise (dashed colored arc) to the first vnode — from there it fans colour into bucket of that vnode’s owner.
Bottom half — the payoff: 4 queues, one consumer each. Keys are placed into the queue the ring assigned and dequeued strictly in order within a queue, while queues 0–3 process concurrently.
Scaling: why not just (mod n)?
(mod (hash k) n) is simpler and does give per-key ordering while n is fixed. The trouble starts when n changes — the modulo re-bases every key’s bucket:
| Key | h | bucket %3 | bucket %4 | moved? |
|---|---|---|---|---|
| K1 | 5 | 2 | 1 | ✅ moved |
| K2 | 7 | 1 | 3 | ✅ moved |
| K3 | 9 | 0 | 1 | ✅ moved |
| K4 | 11 | 2 | 3 | ✅ moved |
| K5 | 13 | 1 | 1 | — same |
| K6 | 15 | 0 | 3 | ✅ moved |
With %, 5/6 keys re-hash elsewhere — every worker must re-route, re-queue, potentially reorder. With a ring that adds a new bucket, only the keys landing inside the new vnodes’ spans move (≈ 1/new-N of them):
Scaling diagram — mod vs ring, 3 → 4 buckets
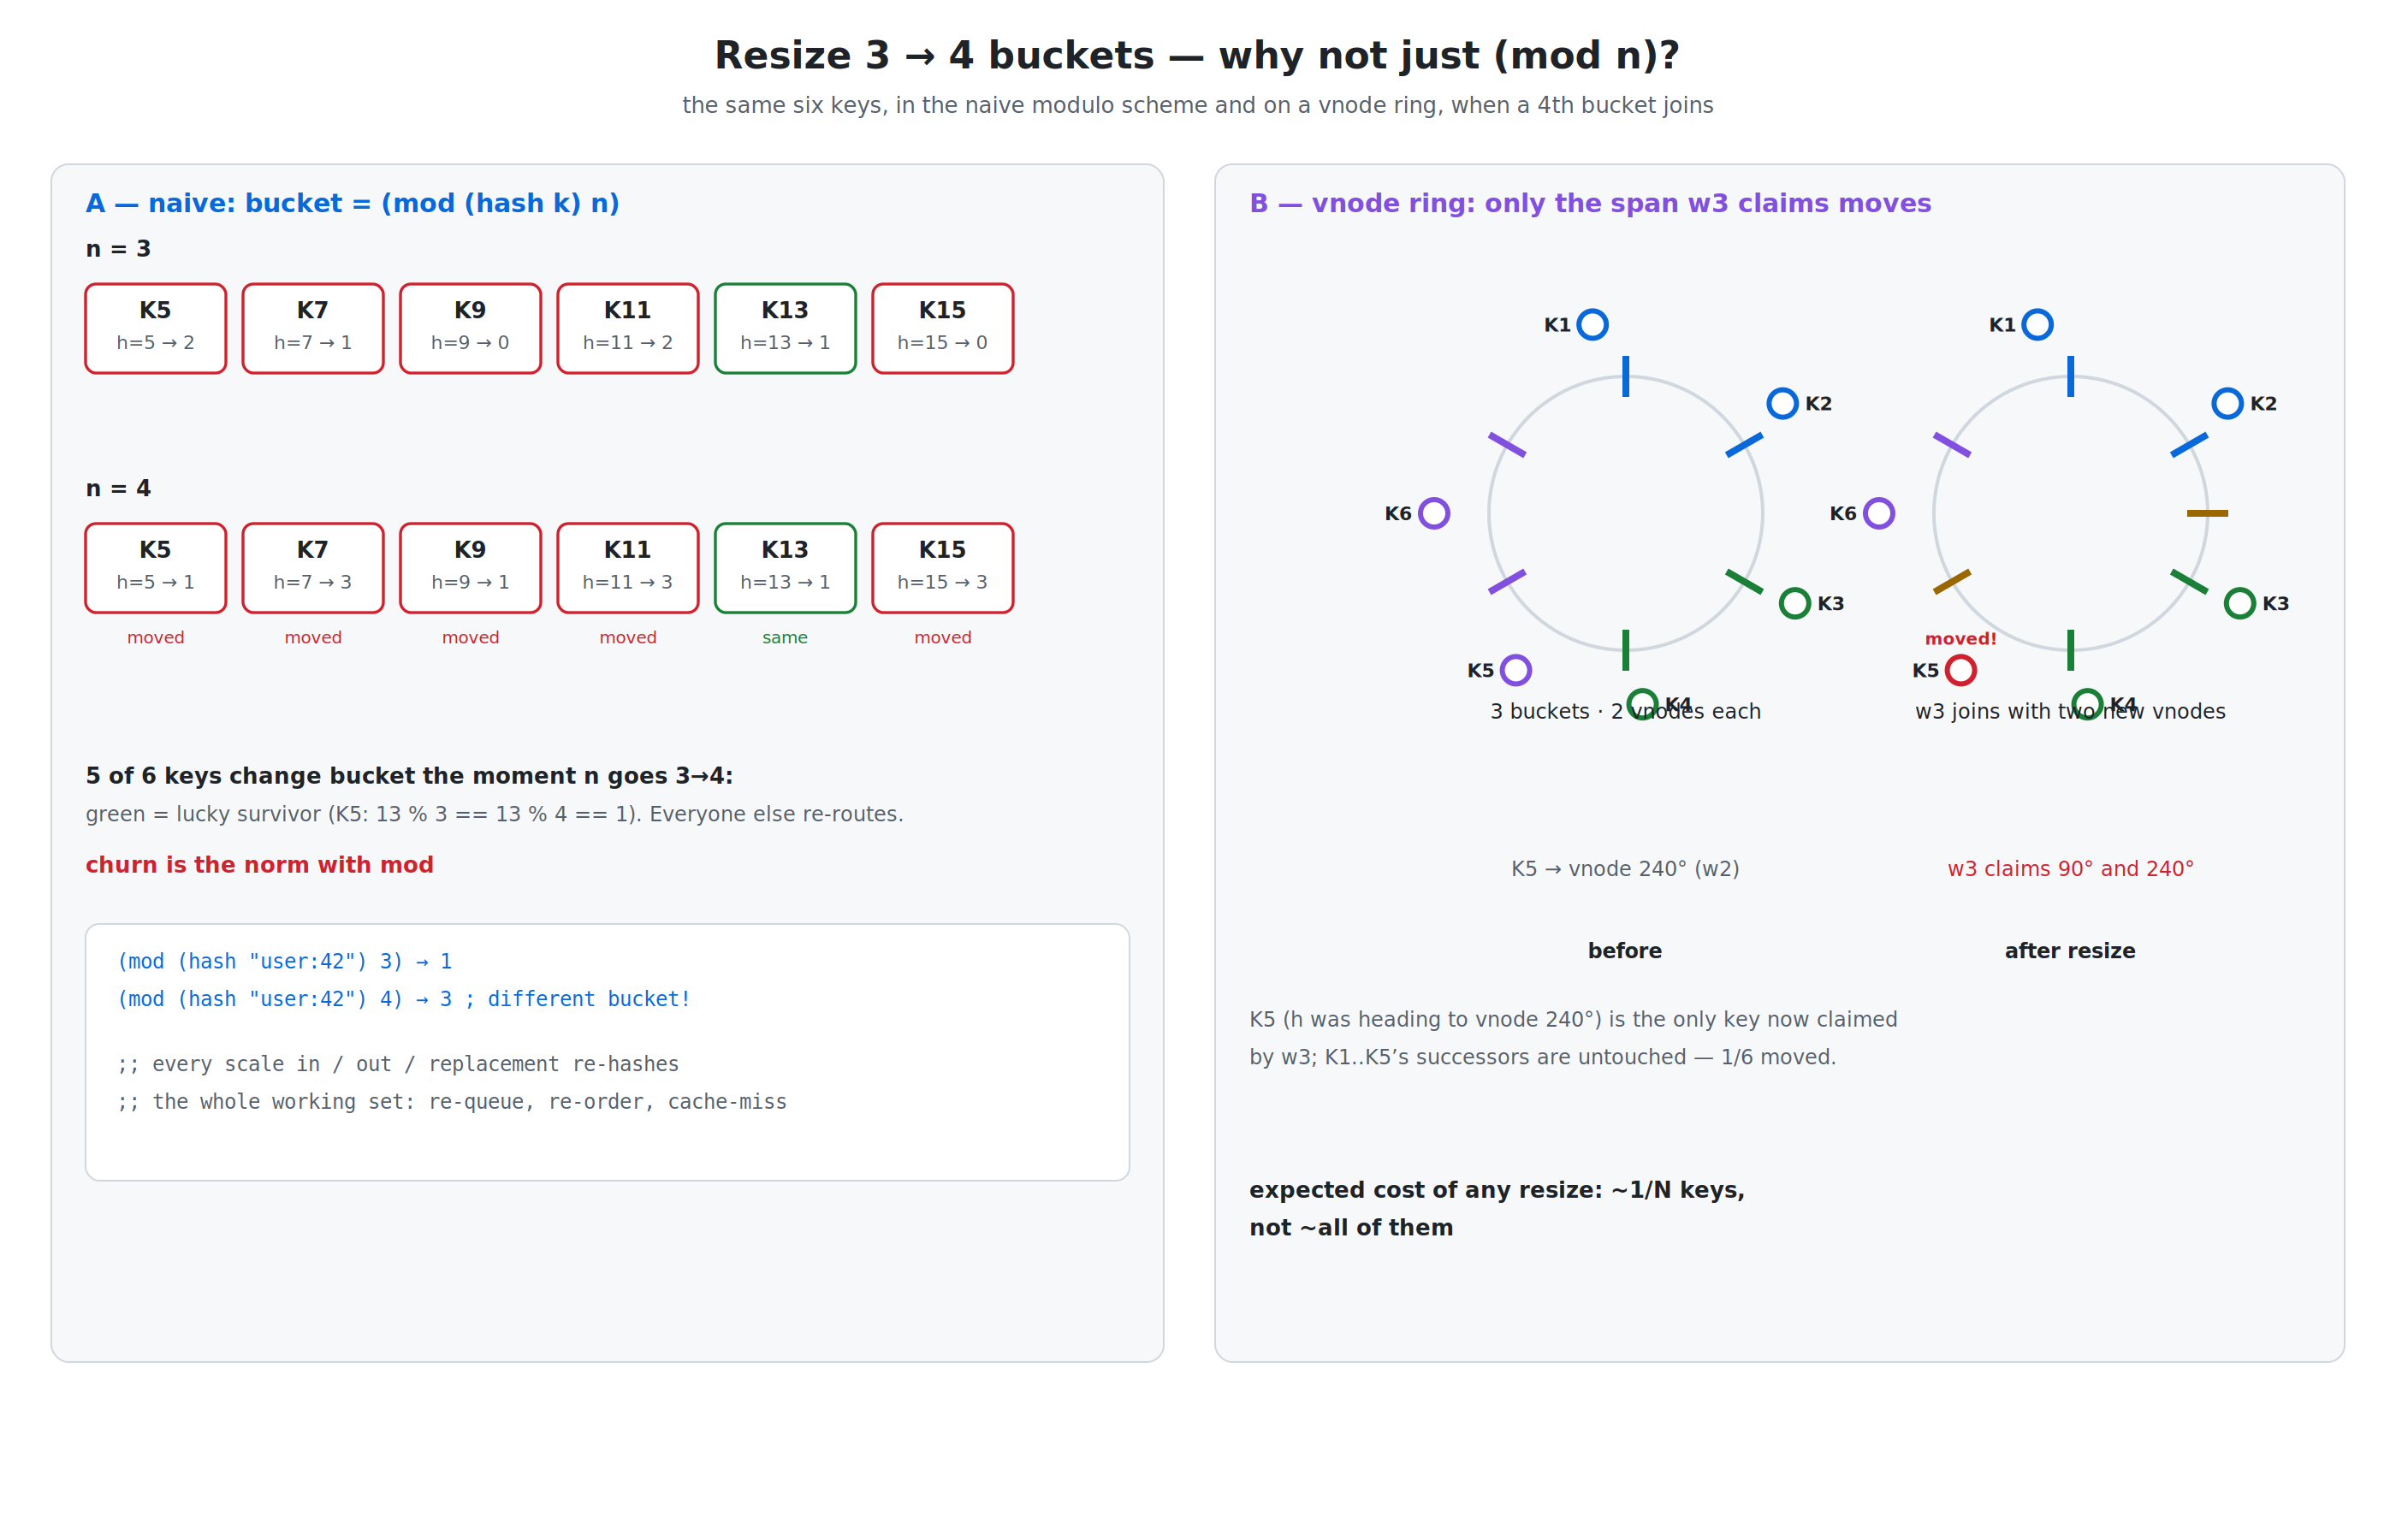
The SVG source is also available in the site repository.
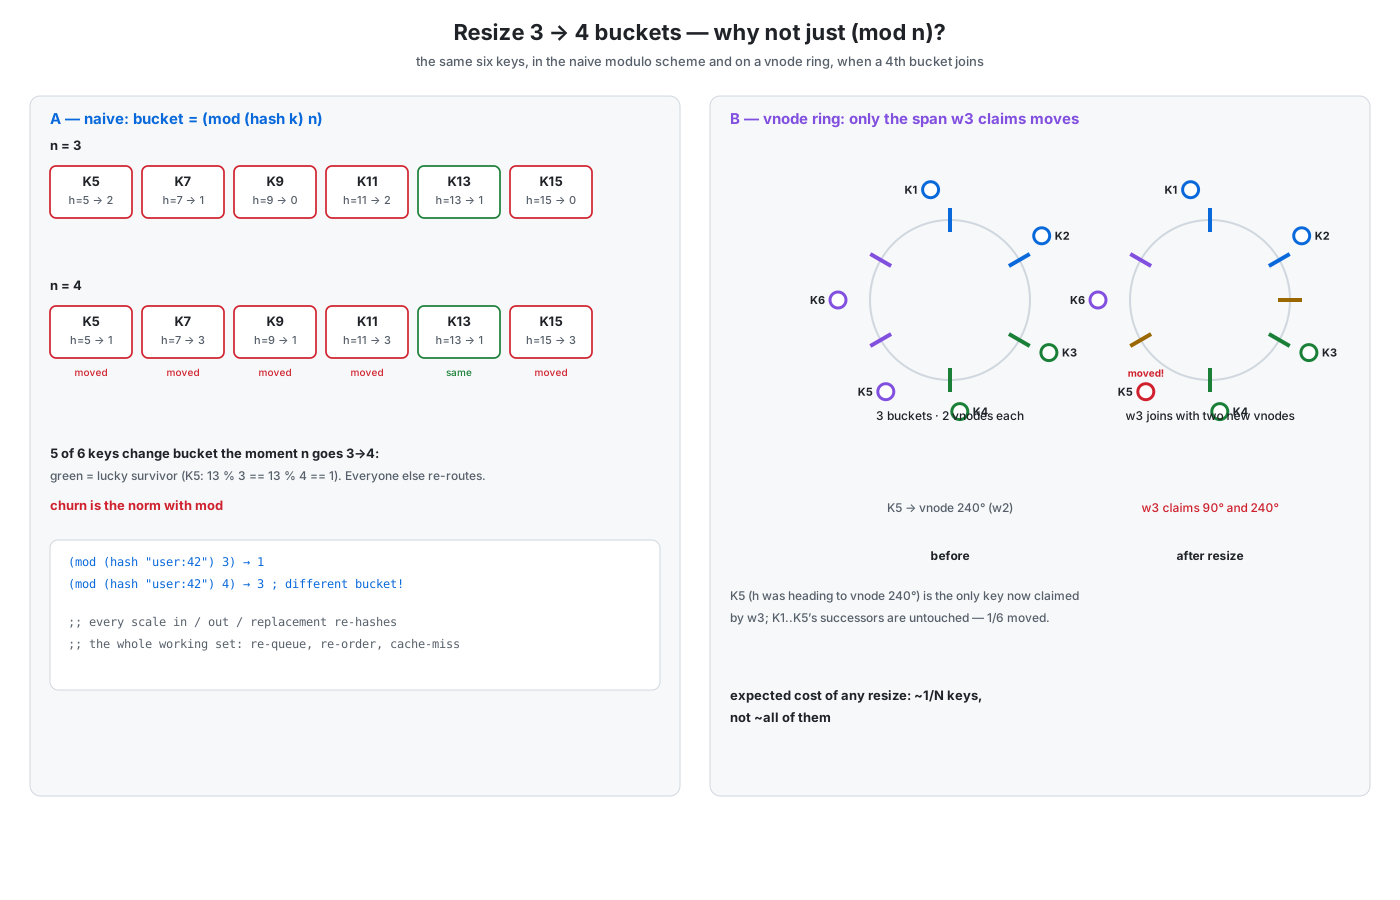
Left panel — mod n: all keys re-bucket; 5/6 move and must be migrated.
Right panel — the ring: w3’s two new vnodes (purple) claim only the keys that hash into those spans — here K5 moves to w3, the other 5 keys stay exactly where they were.
That’s the property you’re buying: about 1/N of keys move per resize — busy systems stay busy, caches keep their hits, and a growing fleet doesn’t churn its entire working set on every scale event.
How Kafka does it
Kafka splits “consumer groups” over partitions of a topic:
- Partition = the unit of ordering and of parallelism. Within a partition, messages are strictly ordered; across partitions nothing is guaranteed.
- The default producer partitioner is not a hash ring: it’s
murmur2(key) % numPartitions(or a sticky partitioner for keys with no value). So Kafka, by default, behaves like the%side of the story above — except its partitions are physical logs, so existing data never moves; only the placement of futurekey → partitionmappings changes when you scale partitions. - A single partition is always consumed by one consumer in a group: that’s the “one worker per bucket” rule that preserves per-key FIFO.
- Since scaling partitions changes the future placement of keys, you only regain a stable mapping via custom partitioners (e.g. those implementing a ring or consistent hash).
The takeaway: Kafka’s ordering machinery (partition → one consumer) is the same shape as the queue-per-bucket pattern; it just picks the bucket with a % instead of a ring by default.
How Cassandra does it
Cassandra is the canonical production hash-ring:
- Each node owns a
num_tokens(default 256) of vnodes, i.e. points on a single 64-bit ring (actual token range-2⁶³ .. 2⁶³-1for Murmur3Partitioner). - Every row’s partition key (
hash(partition_key)) lands on the first vnode clockwise — exactly thebucketfunction above. - Replication: the next
N-1vnodes clockwise (belonging to other nodes) hold replicas — sorf=3reads/write types give key-level availability spread on the same ring data structure. - Scaling: add a node → it takes
num_tokensnew point on the ring, pulling only the tokens ranges those spans cover (≈ ring/Nof the data) — no global re-key. A node leaves → its 256 token-strands’ ownership reassign to several successors — no single-node hot neighbor.
Quick comparison
| Hash ring + vnodes | Mod N | Kafka default | |
|---|---|---|---|
| Lookup | successor walk | h % n | murmur2(k) % partitions |
| Resize | ≈1/N keys move | ~all keys move | existing data stays; future mapping changes |
| Order unit | per bucket | per bucket | per partition |
| Consumer rule | 1/successor | 1/bucket | 1/partition within group |
| Used by | Cassandra, Dynamo, our scraper | simple pools | Kafka core |
Key takeaways
A key's order within one bucket + jobs across buckets = parallelism + ordering.- Ring = routing, not ordering — the ring says which queue; the single consumer per queue is what keeps the key’s messages in order.
- Resize discipline — when the ring changes, keys can move between queues; take care (drain old queues) or you can briefly re-order a hot key’s message.
- Vnodes are the load-leveler — with enough vnodes, skewed hashes and uneven node sizes both balance = with ~1/N churn on scale events.
- Hash choice matters — use uniform 64-bit hash (murmur3);
clojure.core/hashis fine for demonstration, not for a multi-process fleet. - Failures: if a message fails, the whole queue behind it (that key lane) blocks — park-and-retry in order, dead-letter after N attempts; don’t jump in random.